LinkedIn Cuts Daily Spark Shuffle Fetch Failures from 750 to 20 with Apache Celeborn
LinkedIn deployed Apache Celeborn as a shared remote shuffle platform across most Spark and Flink workloads, reducing daily shuffle fetch failures from approximately 750 to 20. The deployment also lowered compute costs by 10%, improved application runtimes by 14%, and reduced shuffle costs per task by nearly 90% through dedicated storage, replication, and data-plane optimizations. By Leela Kumili

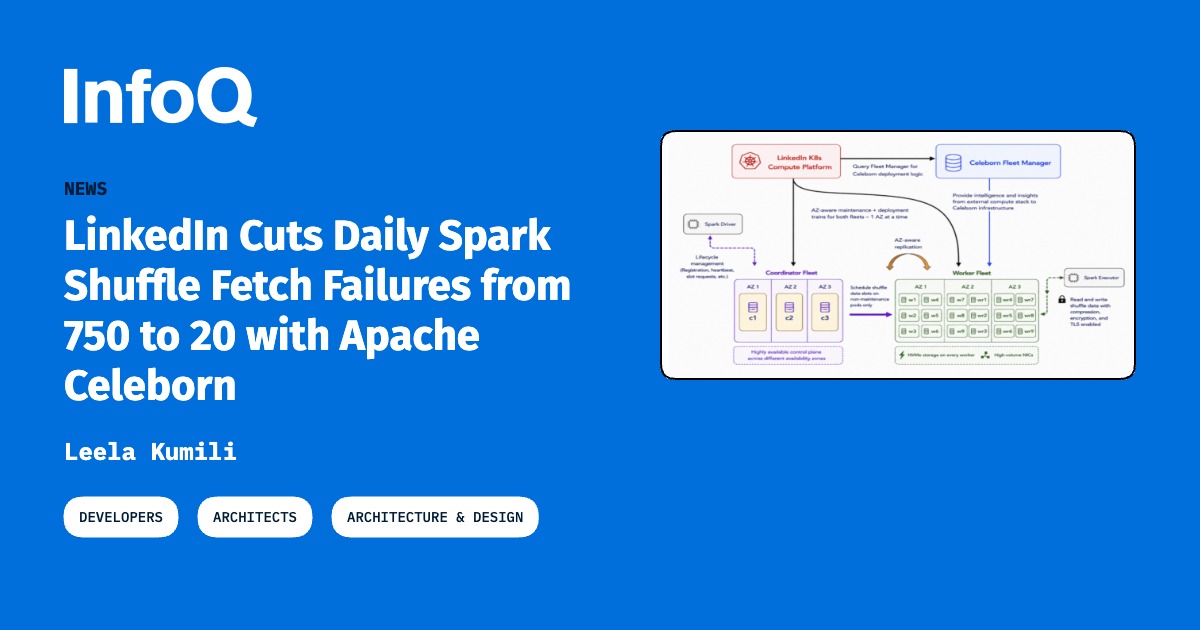

LinkedIn deployed Apache Celeborn as a shared remote shuffle platform across most Spark and Flink workloads, reducing daily shuffle fetch failures from approximately 750 to 20. The deployment also lowered compute costs by 10%, improved application runtimes by 14%, and reduced shuffle costs per task by nearly 90% through dedicated storage, replication, and data-plane optimizations.